Aurora 1.0
Our audio-driven avatar model. One photo and one audio clip become a lifelike talking video, in any language.


Available on
Available on
Most models animate a mouth.
Aurora animates a whole person.
Same photo, same audio, side by side with a competitor.
Here's where Aurora pulls ahead.
Object consistency
Aurora preserves the product's shape and branding as the hand moves. The competitor's object deforms over the clip and generates an incorrect logo on the subject's clothing.
Proven at scale.
videos generated per month
seconds of video (≈465 hrs)
render success rate
Studio quality,without the studio price.
/ second
Transparent, usage-based pricing. Pay by the second, not by the seat or an opaque credit bundle.
480p at $0.07/sec, 720p at $0.14/sec, live on fal with no contract.
Pricing shown for the fal API. Figures pending final confirmation before launch.
One model,
01/04
Marketing
High-converting video ads and UGC at scale, in any language, without a shoot.
02/04
Sales
Personalized video outreach and demos that lift reply and close rates.
03/04
Learning & development
Onboarding, compliance, and training videos, updated in minutes and localized instantly.
04/04
Socials and creators
Faceless channels, podcast cutdowns, and daily posts from a single avatar.
One model, three signals.
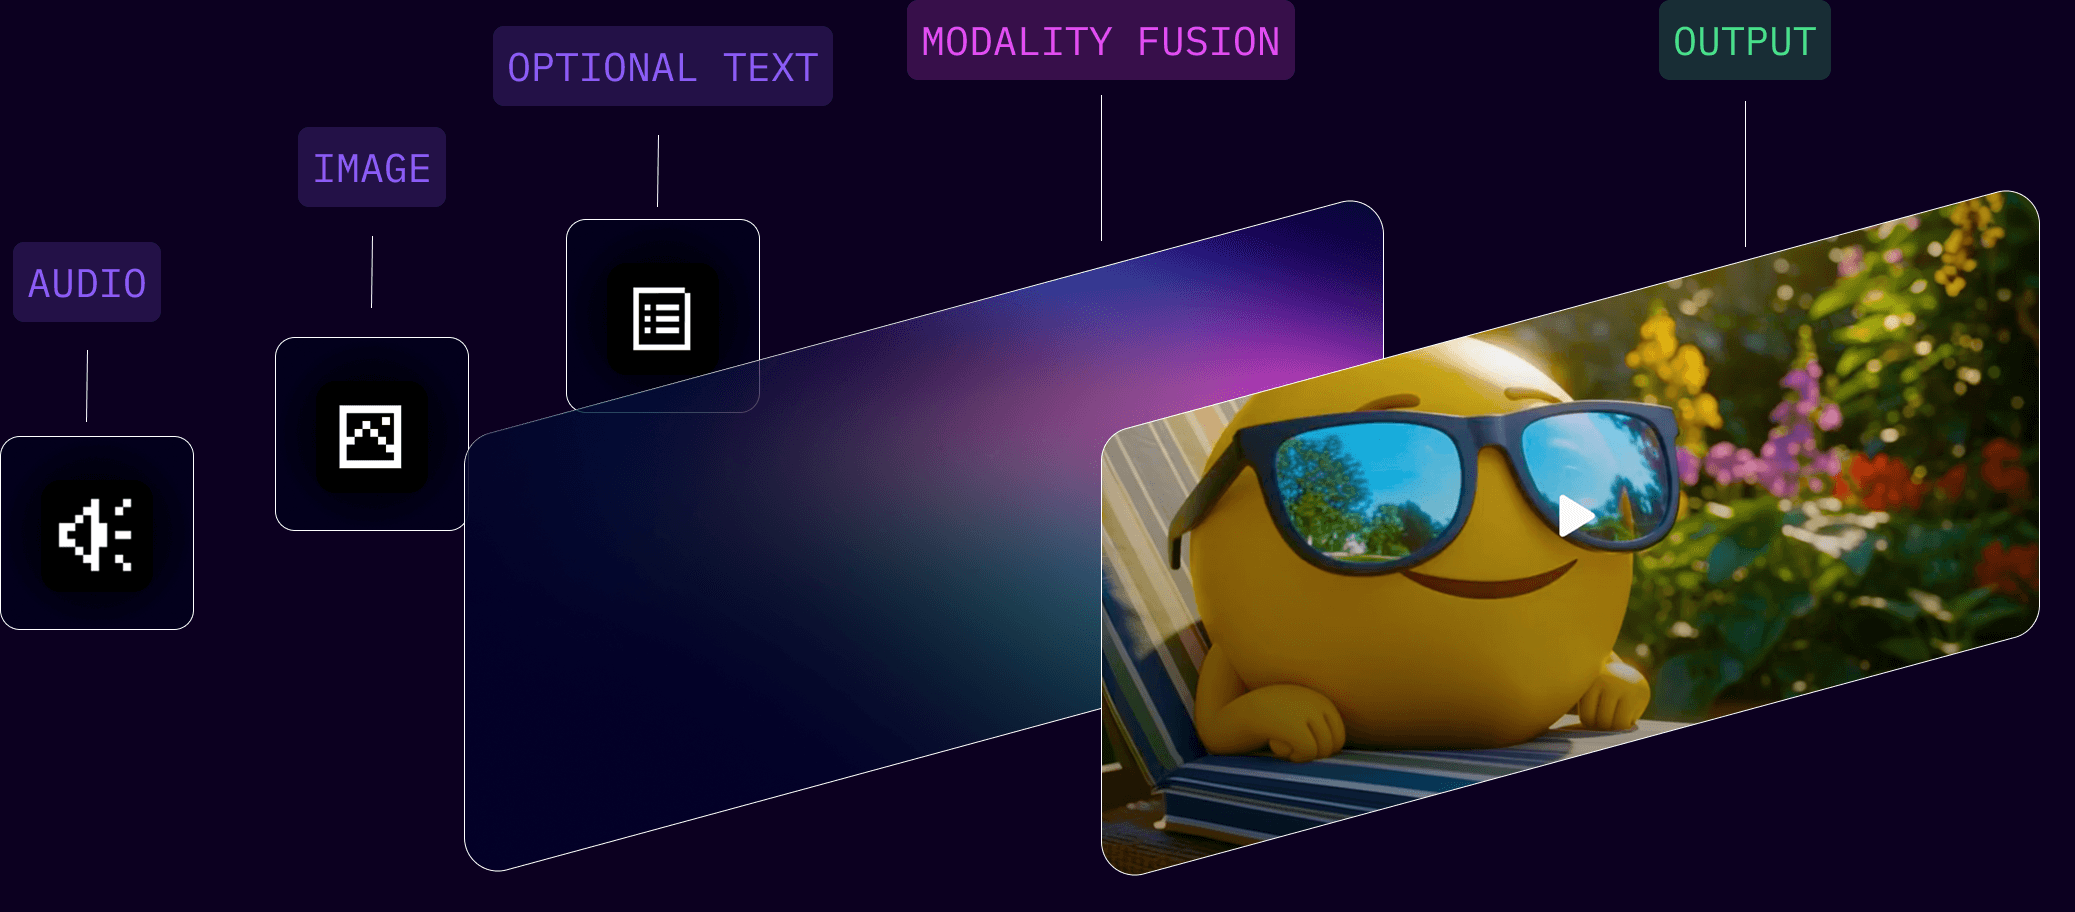
Aurora fuses an image, audio, and text encoder into a shared latent space.
It doesn't just move a mouth. It reads the emotion in the voice and renders the whole performance to match.
Zero-shot, from a single image, with no identity drift.
How Aurora compares.
We put Aurora side by side with leading avatar models across the details that make a video feel human, from breathing to eye contact. Aurora comes out ahead on nearly every one.
Aurora is Creatify Labs' AI avatar model for turning a single photo and an audio clip into a talking video. In head-to-head comparisons against tools like HeyGen, Hedra, and OmniHuman, it leads on lip-sync accuracy, facial expression, natural body movement, and holding fine detail steady over the length of a clip. It generates in any language from your own audio or text to speech, which makes it a strong fit for AI video ads, avatar-led product demos, sales outreach, and training content at scale.
Aurora vs leading models
Independently benchmarked across six metrics. Further out is better.
Tap a model to hide or show it
Q-Align: visual quality · Cost-Eff: cost efficiency · ID-SIM: identity match · LSE-C: lip-sync accuracy · Speed: generation speed · MS: motion smoothness
Quality vs cost per video
Each dot is a model. The best place to be is the top-left: higher quality for lower cost.